
A virtual machine can disappear from a host in seconds, yet the cause may sit several layers below the guest operating system: a failed datastore, damaged virtual disk, broken snapshot chain, deleted configuration file or degraded RAID. The right response in the first hour can determine whether a clean restoration is possible or whether recoverable data is overwritten.
This virtual machine recovery guide is designed for Australian businesses, IT teams and professionals facing an inaccessible VM or critical workload outage. It focuses on protecting the original data first, then choosing the recovery path that offers the best balance of speed, integrity and risk.
Virtual machine recovery guide: first actions
When a VM fails, avoid treating it as an ordinary operating system fault. Repeated boots, automatic repair tools and snapshot changes can write to virtual disks or datastores. If the underlying storage is unstable, those writes may make a later recovery more difficult.
Start by recording the error message, host name, VM name, datastore or storage volume, and the time the issue began. Take screenshots where possible. Check whether other virtual machines on the same storage are affected, but do not make configuration changes simply to test a theory.
The immediate priorities are:
- Stop non-essential write activity to the affected VM, datastore or storage device.
- Confirm whether reliable backups, replication targets or immutable copies exist.
- Preserve the original virtual disk, configuration and log files before attempting repairs.
- Identify whether the fault is isolated to one guest or affects the host, storage array or RAID.
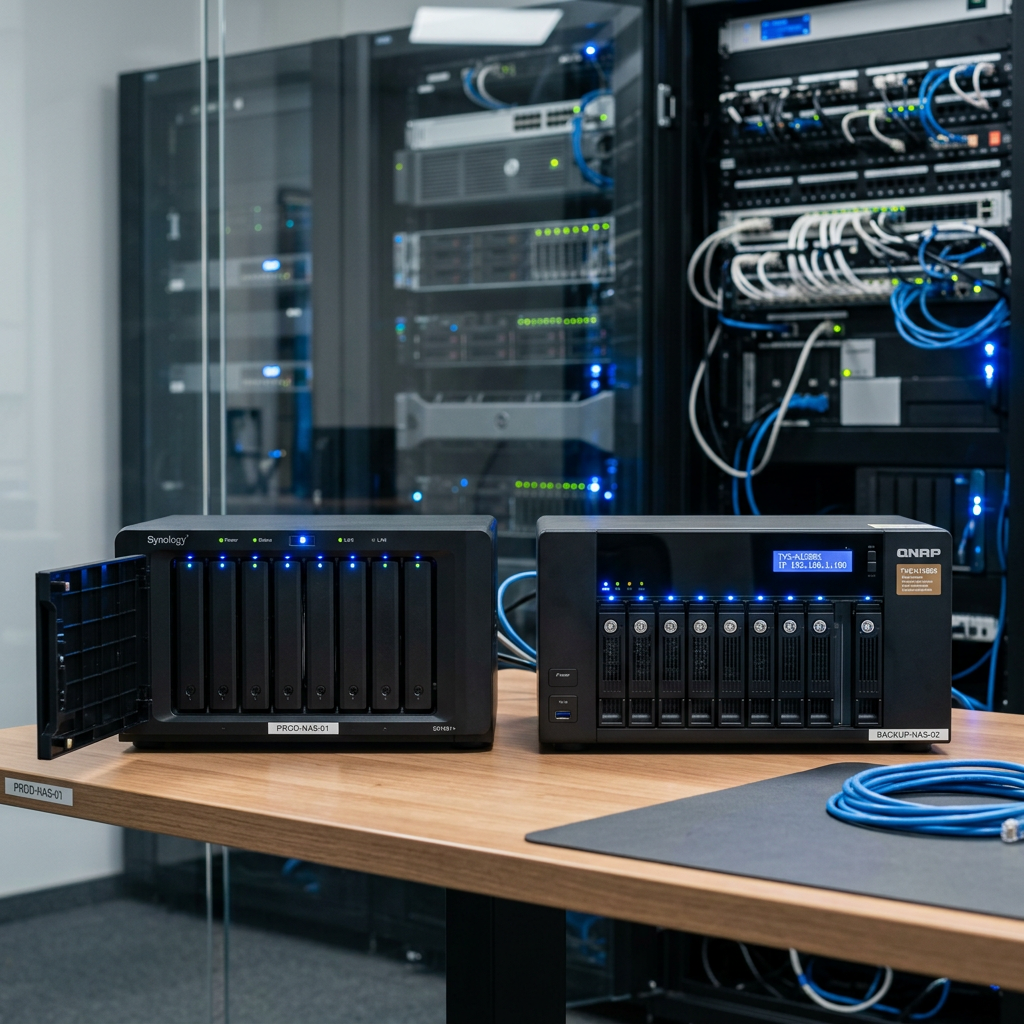
If the VM resides on a physical server with clicking drives, an offline RAID, a failed NAS, an SSD reporting faults or a storage controller error, power cycling may worsen the situation. Shut the affected system down in a controlled way if it is safe to do so, then seek advice before rebuilding arrays, replacing disks or running file-system repairs.
Identify the layer that has failed
Virtual machine recovery is not one process. The correct approach depends on which layer is damaged and whether the source files remain intact.
A guest operating system issue is usually the least complex scenario. The VM starts, but Windows, Linux or an application fails. If a known-good backup or snapshot is available, restoration may be appropriate. However, take care with snapshots: deleting, consolidating or reverting them without understanding the chain can create further problems, particularly when snapshot files are large or the datastore is short of free space.
A virtual disk issue occurs when a VMDK, VHD, VHDX, QCOW2 or similar file is missing, corrupt or no longer recognised. The VM configuration may still be visible, but it may refuse to boot or report disk errors. In this case, preserve every associated file, including descriptor files, delta disks, checkpoint files and metadata. A small descriptor file can be as important as the large data file because it identifies how the disk chain fits together.
A datastore or volume issue affects multiple VMs or prevents the host from seeing storage at all. Common examples include damaged VMFS volumes, inaccessible Hyper-V storage, corrupted ReFS or NTFS volumes, and failed shared storage. The issue may be logical, physical or both.
Finally, a host-level issue can make healthy VM files appear unavailable. A failed hypervisor boot drive, controller problem, network storage outage or licensing/configuration fault may be resolved without recovering the virtual disks themselves. Establish this distinction before copying, repairing or restoring data.
Choose recovery over repair when the source is uncertain
Many platforms offer tools that appear to repair virtual disks, volumes or snapshot chains. These utilities can be useful when the environment is stable, the administrator understands the fault and there is a verified copy of the affected data. They are not risk-free on the only copy of a critical VM.
A safer approach is to work from a clone or image of the source storage wherever possible. That preserves the original state if the first recovery attempt fails. For a single virtual disk, this may mean copying the complete VM folder to separate storage. For a failed RAID, NAS or SAN, a sector-level image may be necessary before file-system reconstruction or virtual disk extraction begins.
Do not assume a backup is usable because a backup job reported success. Check its date, confirm that it contains the required virtual disks and application data, and test whether it can be mounted or restored in an isolated environment. For a business-critical server, consider the recovery point objective as well as recovery speed. Restoring last night's backup may return service quickly but leave a full day of transactions, emails or project files missing.
Recover from backups without creating a second outage
If a verified backup is available, restore the VM to isolated storage or a separate network first where practical. This prevents duplicate IP addresses, domain conflicts and database replication issues when the recovered guest starts.
Before returning it to production, confirm the virtual hardware settings match the original environment. Check CPU and memory allocation, virtual network adapters, firmware mode, boot order and disk controller type. A VM can fail to start simply because it was restored with an incompatible controller or a missing secondary disk.
For database, accounting, practice-management and line-of-business systems, application consistency matters. A VM that boots is not automatically a recovered service. Check database integrity, recent transactions, service accounts, shared folders and scheduled jobs. Ask the application owner to validate key workflows before declaring the incident resolved.
Where backup restoration is incomplete or unavailable, recover the original VM files rather than formatting the datastore or installing a new operating system over the top. Files from the original disk may contain the data needed to rebuild the server, extract documents or restore an application database.
Handle snapshot and checkpoint problems carefully
Snapshots and checkpoints are useful short-term tools, but they are not backups. They rely on a chain of dependent files, and that chain can break after interrupted consolidation, low datastore space, host failure or accidental deletion.
Avoid manually deleting delta files to reclaim space. Do not rename snapshot files, move only part of a VM folder, or use a different VM to write into the same chain. These actions can sever the relationship between base disks and later changes.
Instead, copy the entire VM directory if storage allows, including configuration files, logs, snapshot metadata and all virtual disk components. Record file sizes and modification times. Those details often help establish the correct order of a chain during recovery.
If a snapshot consolidation fails, first protect the available data and confirm free capacity on separate storage. The right remedy could be a controlled clone, an export, a backup restoration or specialist reconstruction. It depends on the platform, disk format and whether the affected storage itself is reliable.
When RAID, NAS or physical storage is involved
A virtualisation problem can be a storage failure in disguise. RAID 5 and RAID 6 arrays may stay online after a disk fault but suffer from degraded performance, read errors or a second disk failure during rebuild. NAS appliances can lose configuration, develop file-system corruption or present empty shares while the underlying disks still contain the VM data.
Do not initialise an unfamiliar RAID set, accept prompts to format volumes, or rebuild an array unless you are certain of its original disk order, RAID level, stripe size and controller settings. A rebuild writes to every disk and can overwrite data needed for recovery. Likewise, replacing a failed drive is sensible only when the array is stable and you have assessed the condition of the remaining drives.
For failed storage containing important VMs, professional data recovery may be the lower-risk option. RecoveryGeeks can assess failed hard drives, SSDs, NAS and RAID systems where the priority is preserving the source data and retrieving critical virtual machine files.
Validate before you hand the workload back
A recovered VM should be tested as a workload, not just as a file set. Keep the original recovered files unchanged while testing a working copy. Boot it in an isolated environment where possible, then inspect operating system logs, storage health, application services and user access.
Check the data people actually rely on: recent documents, customer records, mailboxes, images, project folders or database entries. For servers, verify backups resume successfully after recovery. A restored VM without a functioning backup is still exposed.
Document the incident while it is fresh. Record the cause, affected systems, recovery point, actions taken and any gaps found in backup coverage. This turns a stressful outage into useful evidence for improving retention, monitoring, capacity planning and recovery testing.
When the cause is unclear, the storage is showing physical faults or the data cannot be replaced, pause before trying another repair command. Protecting the original VM files gives you more recovery options, and often makes the path back to service far less costly.
