
A deleted database is rarely just a missing folder. It may hold customer records, accounting data, job files, emails or the system behind an essential business application. Knowing how to recover deleted databases starts with one priority: stop activity that could overwrite the data or make a clean recovery harder.
The correct recovery method depends on what was deleted, where it was stored, and which database platform was involved. A database removed from Microsoft SQL Server needs a different response from a deleted MySQL schema, PostgreSQL cluster, cloud database or application database on a failed NAS. Acting carefully in the first hour can make a material difference.
First actions after a database is deleted
Do not create a new database with the same name, restart services repeatedly, run disk-cleaning tools, or install recovery software on the affected server or drive. These actions can overwrite data blocks, change transaction logs, or complicate forensic assessment.
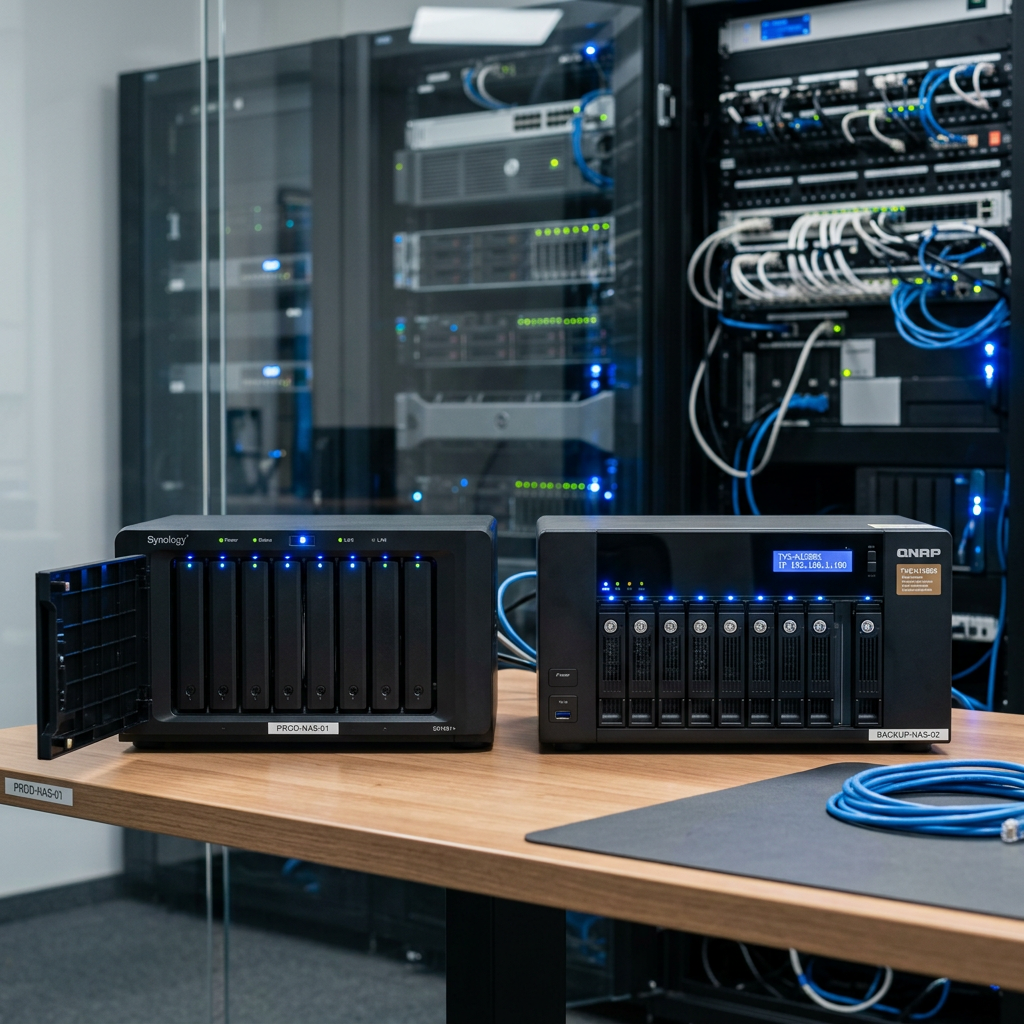
If the database is on a virtual machine, avoid taking actions that cause high disk activity. If it sits on a NAS or RAID, stop rebuild attempts and do not replace drives without documenting the original order and configuration. A RAID rebuild writes across the array and may reduce the chance of recovering deleted database files.
Before attempting any repair, record what happened. Note the database engine and version, the time of deletion, the server name, storage location, recent backup history, error messages and any commands that were run. This information helps an IT team or recovery specialist choose the safest path.
How to recover deleted databases from backups
A verified backup is normally the cleanest and most reliable recovery option. However, restoring the most recent full backup may not be enough if the business needs transactions made after that backup was taken.
For many systems, recovery follows a sequence: restore a full backup, restore a differential backup if one exists, then restore transaction or write-ahead logs up to the required point in time. This can allow recovery to just before an accidental `DROP DATABASE`, table deletion or damaging query occurred.
Confirm what your backup actually contains
Check that the backup is readable and that it includes the affected database, not only server settings or selected files. Confirm its date, the database version it was created from, encryption requirements, and whether the backup chain is complete.
A backup can appear successful while being unsuitable for restoration. Common issues include an expired cloud retention period, missing transaction logs, an unavailable encryption key, corrupted backup media, or a backup that was taken after the deletion occurred.
Where possible, restore to a separate server, virtual machine or isolated instance first. This protects the current environment and gives you an opportunity to validate the recovered data before switching production systems back online. Check row counts, recent records, user permissions, application connectivity and reporting output rather than assuming a successful restore means every requirement has been met.
Point-in-time recovery
Point-in-time recovery is often the best outcome for accidental deletion, but only where the database engine and logging configuration support it. SQL Server transaction log backups, PostgreSQL write-ahead log archives, MySQL binary logs and managed cloud database recovery features can provide a path back to a chosen time.
The trade-off is that transactions after the selected recovery point may be lost. For example, recovering to 10:14 am to reverse a deletion at 10:15 am will usually exclude changes made after 10:14 am. The recovery target should be chosen with the relevant business team, especially where orders, payments, bookings or compliance records are involved.
When the database files were deleted from storage
If there is no usable backup, the recovery effort moves from database restoration to storage-level recovery. This is more technical and the outcome depends heavily on the storage device and what happened after deletion.
Traditional hard drives may retain deleted database files until their sectors are overwritten. SSDs are less predictable because TRIM and internal garbage collection can clear deleted blocks quickly. On a NAS, SAN or RAID system, the database may be spread across multiple disks and protected by a filesystem or volume manager that adds further complexity.
Database files are not always useful in isolation. A typical system may require data files, log files, control files, configuration files and specific metadata to start correctly. Recovering only one file from a deleted database folder can be insufficient, and attempting to attach damaged files to a live server may worsen corruption.
For a server with failed drives, RAID degradation, unusual clicking sounds, inaccessible volumes or a controller fault, power it down if doing so will prevent further damage. Do not run repair utilities, initialise disks, format the volume, or accept a prompt to rebuild a filesystem. These tools are designed to make storage usable again, not to preserve deleted evidence.
RecoveryGeeks can assess failed hard drives, SSDs, NAS devices and RAID systems where the database loss is linked to physical storage failure or inaccessible media. In these cases, preserving the original devices and configuration is essential.
Database-specific recovery considerations
The database platform changes the available recovery options. An experienced administrator will consider the engine's backup format, logging model, storage layout and recovery controls before making changes.
Microsoft SQL Server
For SQL Server, check for full, differential and transaction log backups, including copies held by backup software or offsite retention systems. If the database was dropped, point-in-time restoration may be possible when the transaction log chain is intact and the database uses the full or bulk-logged recovery model.
Avoid attaching unknown MDF and LDF files to a production instance. Copy files first where possible, and treat repair commands as a last resort. Some repair operations can remove damaged pages or objects to make a database consistent, which may mean permanent data loss.
MySQL and MariaDB
MySQL and MariaDB recovery may involve restoring a logical dump, filesystem-level backup, binary logs, or InnoDB data and log files. Binary logs can be especially valuable for replaying changes after a backup, but only if logging was enabled and the necessary files remain available.
Do not assume that copying individual table files will restore an InnoDB database. InnoDB maintains internal metadata and shared structures, so recovery can require a matched set of files and compatible server settings.
PostgreSQL and cloud databases
PostgreSQL commonly relies on base backups and archived write-ahead logs for point-in-time recovery. If WAL archiving was not configured, the recovery window may be limited to available backups.
For managed cloud databases, check the provider's restore points, snapshots, recycle-bin features and retention settings immediately. Creating a restored copy is usually safer than replacing the live instance. Be aware that automated snapshots can have short retention periods, so a delay may close off the simplest recovery option.
Avoid the common mistakes that reduce recovery chances
The pressure to get systems running again can lead to decisions that permanently change the evidence. Avoid these actions unless you have a tested recovery plan and understand the consequences:
- Running CHKDSK, fsck, database repair utilities or filesystem repair tools on the original storage.
- Reusing the affected disk, virtual disk or cloud volume for new data.
- Rebuilding a degraded RAID array before capturing its configuration and assessing each drive.
- Restoring over the only available copy of the current database environment.
- Assuming a backup is valid without testing the restore.
A controlled recovery takes longer than a quick fix, but it reduces the risk of turning a recoverable deletion into a permanent loss.
Validate the recovery before returning to service
Once a database has been restored or reconstructed, validate more than its ability to open. Check application functions, recent transactions, key reports, permissions, scheduled jobs, integrations and data consistency. Ask the people who use the system daily to verify critical records and workflows.
Keep the recovered copy separate until stakeholders approve it. If records are missing between the backup time and the deletion event, those transactions may need to be reconstructed from application logs, emails, payment systems, exports or other source records.
A deletion incident is also a useful test of the organisation's backup design. After recovery, review backup frequency, retention, offsite copies, restore testing, access controls and alerting. The best time to find out whether a backup works is not during the next emergency.
When the database is business-critical, the storage is failing, or there is no clean backup path, pause before experimenting. Preserving the original system and getting specialist advice early gives you the best chance of recovering the data that matters.
