
A server share goes offline at 8:40 am. The finance folder will not open. Your project files are missing from a portable SSD. A RAID volume starts showing errors just before payroll or a client deadline. When you need to recover business files urgently, the first hour matters more than most people realise.
The wrong move can turn a recoverable problem into permanent data loss. The right move can preserve critical evidence on the device, reduce downtime, and give a recovery specialist the best possible chance of retrieving your files intact. Urgency is real, but panic is expensive.
What urgent business file loss usually looks like
Business data emergencies rarely arrive with much warning. In some cases, a staff member deletes the wrong folder or empties a recycle bin without noticing. In others, the issue is technical: a failed SSD controller, a hard drive with bad sectors, a corrupt NAS volume, a degraded RAID, power damage, or a device that has simply stopped being detected.
The symptoms can look similar even when the causes are very different. Files may disappear, folders may rename themselves, systems may freeze during access, or you may receive prompts to format a drive. That last message is one of the most dangerous because it can make a damaged device seem fixable with one click. It often is not.
For businesses, the stakes are higher than simple inconvenience. Lost files can interrupt quoting, production, invoicing, legal work, design delivery, medical records access, and internal operations. A sole trader may lose this week’s income. A larger organisation may lose access to shared business-critical data across multiple staff.
If you need to recover business files urgently, stop using the device
The first practical step is also the one people resist. Stop writing new data to the affected device immediately. Do not keep rebooting it to see if it comes back. Do not run cleanup utilities. Do not install recovery software onto the same drive you are trying to recover from.
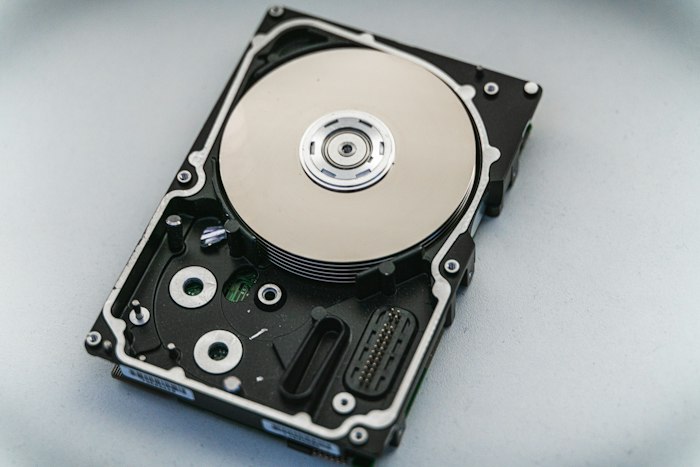
Every additional write can overwrite deleted files or stress damaged hardware further. This is especially relevant with SSDs, where background processes and TRIM behaviour can change the recovery picture very quickly. With traditional hard drives, continued operation can worsen platter or head damage. With RAID and NAS systems, well-meant rebuild attempts can alter the array state and complicate recovery.
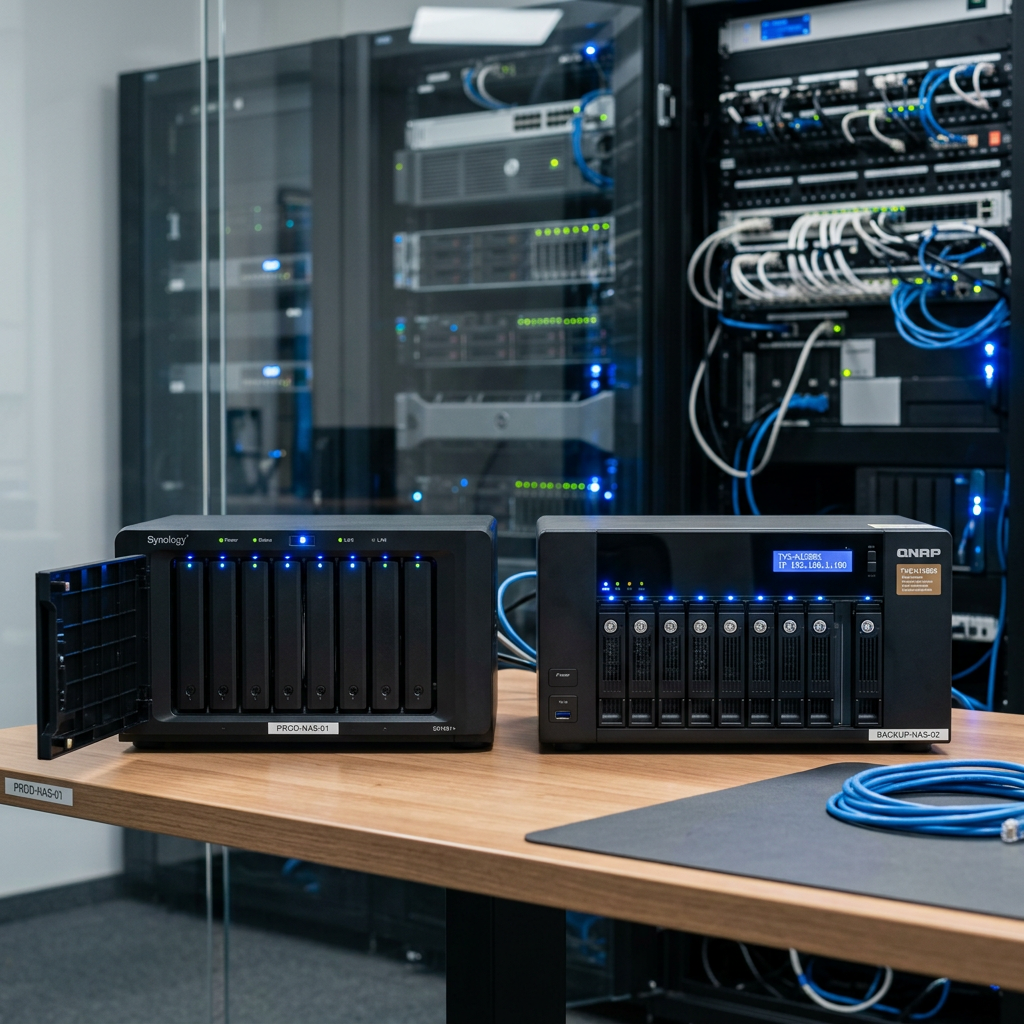
If the affected data sits on a server, NAS, or RAID, isolate the issue calmly. Make note of drive order, slot position, warning lights, unusual noises, and any error messages. If there is a recent backup, verify it before doing anything else. A backup that has not been tested is only a theory.
What to do in the first 60 minutes
Start by identifying whether this is a logical issue, a hardware issue, or a system issue. You may not know for certain, but you can gather useful clues. Can the device be seen by the computer but not opened? Does it make clicking or beeping sounds? Did the problem follow a power outage, drop, liquid exposure, or sudden disconnect? Is only one staff member affected, or the whole office?
Document what happened just before the failure. That timeline helps recovery work more than many people expect. If the files were on a business laptop, external drive, NAS, RAID, or desktop, record the device type, brand, capacity, operating system, and any recent changes such as updates, shutdown issues, or failed transfers.
Then decide whether the device should remain powered on. If a server or NAS is actively degrading, there is no universal rule. Sometimes a controlled shutdown protects the hardware. Sometimes keeping a system state unchanged until an expert review is the safer path. It depends on the storage architecture, whether redundancy is already compromised, and whether there is current risk of further damage.
That is why business cases often benefit from speaking with a specialist early rather than relying on generic internet advice written for home USB drives.
The most common mistakes in urgent file recovery
The biggest mistake is treating all data loss as software deletion. Businesses often download a recovery app because it feels fast and economical. Sometimes that works for straightforward accidental deletion on a healthy drive. Often it does not, especially when the device has physical faults, file system corruption, RAID complexity, or encryption in the mix.
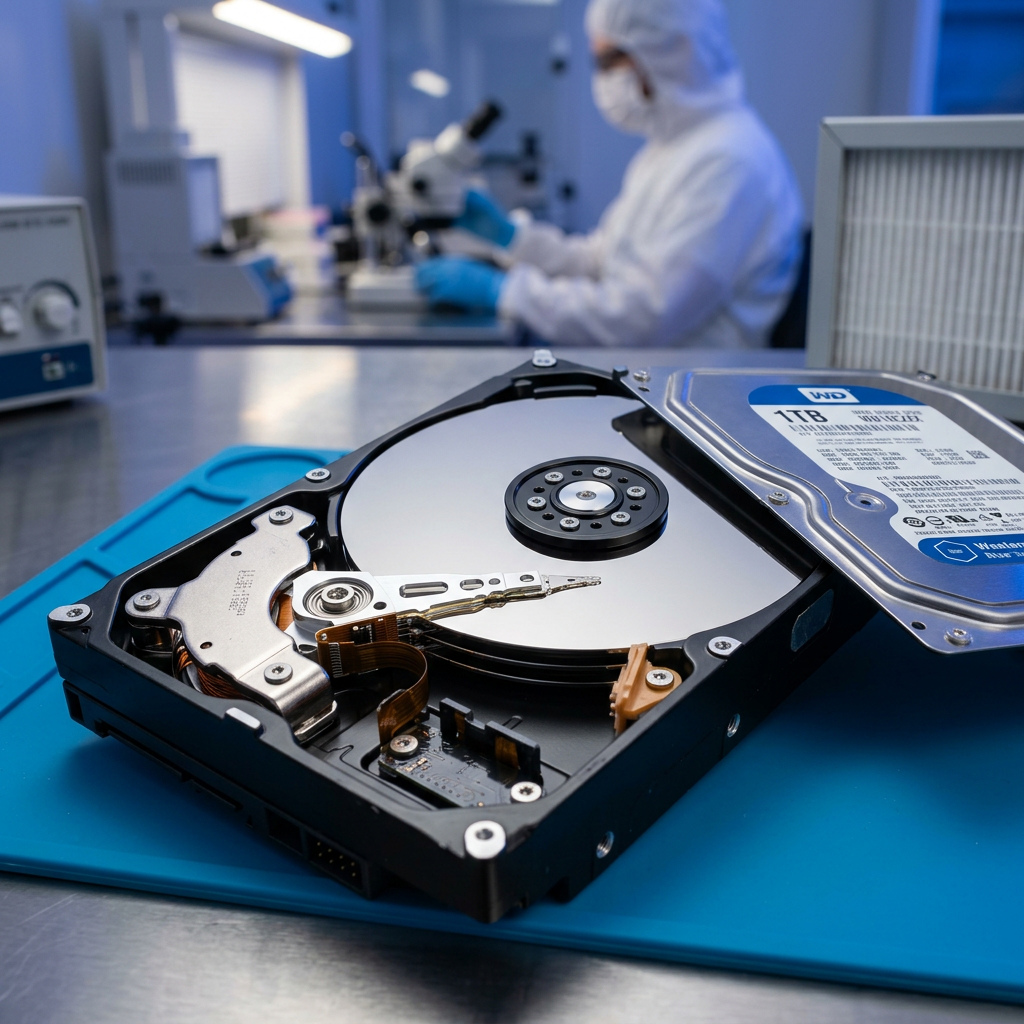
Another common mistake is swapping parts, opening a drive, or letting a general repair shop experiment. Modern storage devices are not forgiving. Hard drives require controlled clean conditions for internal work. SSD recovery can involve specialist board-level and controller-specific processes. RAID recovery depends on accurate reconstruction of array parameters and member drive behaviour. Guesswork wastes time and can reduce recovery options.
There is also a business continuity mistake: focusing only on the device, not the operational impact. While the technical assessment is underway, someone in the business should identify what is missing, what deadlines are affected, what clients may need updates, and whether partial workarounds exist. Recovery is technical, but the response should be operational as well.
When DIY makes sense, and when it does not
There are cases where internal action is reasonable. If a healthy drive is fully accessible and someone has simply deleted files recently, a cautious read-only review or recovery process may be worth considering. The key word is healthy. No abnormal noises, no detection issues, no corruption prompts, no signs of electrical or physical damage.
For urgent business cases, that window is narrower than many assume. If the data has commercial value, legal significance, compliance implications, or would cause serious downtime if lost, professional assessment is usually the safer path from the outset. The cost of failed DIY attempts is not just technical. It can be measured in missed work, staff time, reputational damage, and delayed decisions.
This is particularly true for NAS and RAID environments. A RAID 5 or RAID 6 issue may appear survivable because redundancy exists on paper, yet one wrong rebuild or drive reseat can change everything. The same applies to SSDs holding accounting systems, design assets, databases, or virtual machine files. These are not ideal places to experiment.
Device type changes the recovery approach
A failed hard drive, a dead SSD, and a corrupted NAS can all present as inaccessible files, but they are not the same job. Hard drives may suffer mechanical, firmware, or media issues. SSDs often involve controller, firmware, encryption, or NAND-related complications. NAS devices introduce file systems, shared access, multi-disk structures, and sometimes proprietary configurations. RAID systems add stripe size, parity, disk order, failed member behaviour, and rebuild history.
Apple devices, external drives, camera media, and business laptops each bring their own variables too. FileVault, BitLocker, proprietary photo formats, damaged connectors, and accidental formatting all change what is possible and how quickly it can be done.
That is why category-specific expertise matters. A technician who mostly swaps laptop screens is not the same as a specialist who handles failed SSDs, damaged hard drives, and multi-drive business storage under pressure.
How professional urgent recovery usually works
A proper urgent recovery process starts with assessment, not assumptions. The goal is to identify the failure type, stabilise the media where possible, and choose the least destructive path to the data. In business cases, speed matters, but controlled speed matters more.
For logical damage, recovery may focus on file system repair in a controlled environment, reconstruction of metadata, or extraction of accessible data to safe media. For hardware faults, the device may require advanced imaging, firmware work, or component-level intervention before file extraction can even begin. For RAID and NAS cases, the work may involve virtual reconstruction and validation before recovery output is produced.
Good recovery work also keeps chain of custody, privacy, and business sensitivity in view. Many businesses are not only worried about whether files can be recovered, but who handles them, how they are stored during the process, and how quickly usable results can be returned.
For Canberra businesses and organisations elsewhere in Australia, working with a specialist service such as RecoveryGeeks can make that process clearer because the assessment is anchored in actual device and storage expertise, not a generic repair script.
How to reduce downtime while recovery is underway
Urgent recovery is not only about the damaged device. It is also about keeping the business moving. Assign one person to liaise with the recovery provider and another to coordinate internal workarounds. Pull recent email attachments, exported reports, local sync copies, or version histories from unaffected systems if they exist. Confirm what can be recreated quickly and what cannot.
Be careful here as well. Do not confuse substitute working files with the originals under recovery. If a team starts rebuilding data, label those files clearly so they do not create version conflicts later. This sounds minor until two weeks of recreated work collides with recovered originals and nobody knows which is current.
A stressful recovery job is also a useful test of your backup and storage design. Not every failure can be prevented, but many business disruptions can be softened with verified backups, role-based storage practices, and clearer escalation paths.
When business files disappear at the worst possible time, the best response is calm, fast, and technically disciplined. Protect the device, capture the facts, and get the right eyes on it early. That gives your data the best chance, and it gives your business room to breathe while the recovery work begins.
