
When a RAID goes down, the problem is rarely just a failed drive. It can mean accounting files are offline, project data is inaccessible, backups are incomplete, and a business day starts slipping away. This guide to RAID data recovery is written for the moments when speed matters, but so does getting the next step right.
RAID failures are stressful because they often sit at the centre of important systems - NAS units, file servers, surveillance storage, virtual machines, and creative archives. Many people assume RAID automatically prevents data loss. Sometimes it helps with uptime, but it does not replace backup, and it certainly does not make a damaged array easy to rebuild under pressure.
What RAID data recovery actually involves
RAID data recovery is the process of reconstructing data from multiple drives that were previously working together as one logical storage system. That sounds simple until you factor in RAID level, controller behaviour, drive order, stripe size, parity rotation, file system damage, firmware issues, and the possibility that more than one problem is happening at once.
In practice, successful recovery depends on identifying the original array layout before any repair attempt changes it. A RAID 5 with one failed drive is very different from a RAID 10 with controller corruption or a NAS where the disks are healthy but the file system metadata is damaged. The recovery path depends on the cause, not just the symptom.
That is why a proper guide to RAID data recovery starts with restraint. The first job is not to force the array online. It is to preserve the current state of every drive and avoid making the damage worse.
The most common causes of RAID failure
Physical drive failure is the obvious one, but it is only part of the picture. RAID arrays also fail because of controller faults, accidental reconfiguration, power events, firmware bugs, bad sectors across multiple disks, failed rebuilds, and human error during maintenance.
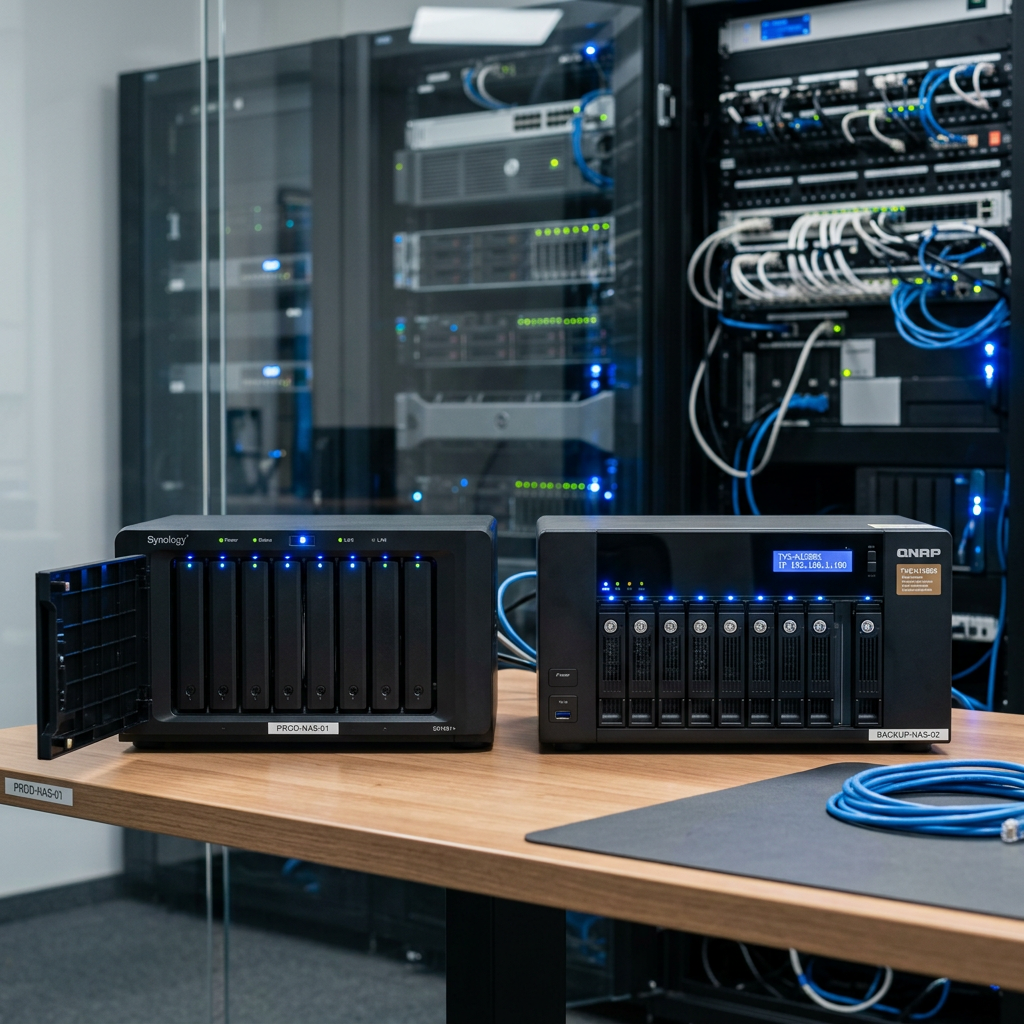
NAS-based RAID systems add another layer. You might be dealing with proprietary metadata, a Linux-based file system, or a degraded volume that becomes inaccessible after a reboot. In business environments, failed updates, dropped arrays in virtualised platforms, or a second drive failing during rebuild are common turning points.
There is also a trade-off worth understanding. The more complex the environment, the less useful guesswork becomes. A desktop RAID enclosure used for media storage may be relatively straightforward. A multi-bay business NAS with snapshots, encrypted volumes, and mixed-age disks is not.
First steps after a RAID failure
If the array contains important data, stop using it. Continued operation can overwrite metadata, trigger an unstable rebuild, or push a marginal drive into complete failure. If a rebuild has already started and the array is behaving unusually, that is often the point where professional advice is worth seeking before proceeding.
Take note of what changed just before the failure. A power outage, a drive replacement, unusual noises, a firmware update, or an accidental reset can all be significant. Record drive positions, serial numbers, error messages, and RAID settings if they are visible. Do not shuffle drives between bays. In many cases, original disk order matters.
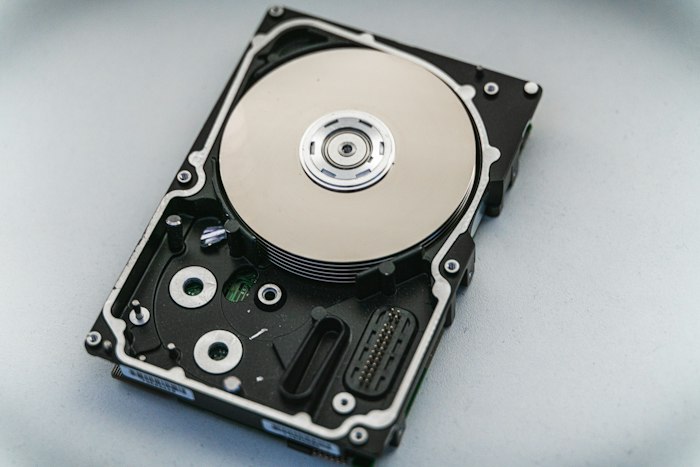
If a drive is clicking, not spinning, or dropping in and out, avoid repeated power cycles. Physical issues require a different handling process from logical corruption. Forcing a sick disk through multiple retries can reduce the chance of a stable image later.
What not to do
The biggest mistake is treating RAID like a normal external drive. Standard file recovery software may scan individual disks and return fragments, but it usually cannot make sense of a damaged array without correct RAID parameters. Worse, some tools encourage writes, repairs, or rebuild actions that alter source data.
Be cautious with these actions:
- replacing more drives before confirming the array state
- initialising disks when prompted by the operating system
- running CHKDSK, fsck, or similar repair tools on an unstable array
- accepting automatic rebuilds without confirming the correct member disk set
- updating firmware during an active failure
Any one of these can shift the problem from recoverable to significantly harder. RAID recovery is often possible after a serious fault, but every write to the member disks reduces room to work.
A practical guide to RAID data recovery by failure type
Single-drive failure in a redundant RAID
If you have RAID 1, RAID 5, RAID 6, or RAID 10, one failed drive does not always mean immediate data loss. But degraded operation is not safe operation. The remaining drives are under more strain, and if one of them has bad sectors or latent damage, a rebuild can collapse the array.
This is where many recoveries become more complicated. A business sees one failed disk, swaps it out, starts rebuilding, and only then discovers another member has unreadable sectors. At that point, parity may no longer be enough to reconstruct the missing blocks cleanly.
Multiple-drive failure or failed rebuild
This is one of the more serious scenarios. A RAID 5 that loses two members, or a RAID 6 with broader underlying damage, generally needs controlled recovery work rather than in-system repair. The goal is usually to image each drive, assess readable sectors, determine the original RAID parameters, and reconstruct the array virtually rather than relying on the hardware to do it live.
A failed rebuild is particularly risky because the array metadata may have changed during the process. Recovery then depends on both the pre-failure structure and what the rebuild altered.
Controller, NAS, or metadata failure
Sometimes the disks are mostly intact and the issue is the enclosure, controller, or configuration data. This can happen after power faults, firmware problems, or board failure. Swapping drives into a new device is not always safe, especially across different models or firmware generations.
In these cases, recovery often involves working directly with the disks outside the original hardware, identifying array parameters manually, and mounting the reconstructed volume in a controlled environment.
Why RAID level matters so much
RAID 0 offers performance, but no redundancy. Lose one disk and the whole volume becomes incomplete. RAID 1 mirrors data, which can make recovery simpler if one side is healthy, though file system damage can still affect both. RAID 5 and RAID 6 rely on parity, which means recovery accuracy depends on correct stripe and parity interpretation. RAID 10 combines mirroring and striping, and its recoverability depends on which disks failed and how the mirrors were paired.
Nested and proprietary RAID setups add complexity. Some NAS vendors use customised layouts or hidden system partitions. That does not make recovery impossible, but it does mean the process is more technical than simply reading files from one disk.
When professional RAID recovery is the better option
If the data is commercially important, time-sensitive, or not fully backed up, professional help is usually the safer choice early rather than late. That is especially true when there are signs of physical disk issues, multiple failed members, accidental reconfiguration, or an interrupted rebuild.
A specialist approach normally starts with non-destructive imaging. Each disk is captured sector by sector as far as possible, unstable media is handled carefully, and the array is rebuilt in software using the imaged data rather than the original drives. That protects the source and allows different reconstruction options to be tested without further risk.
For Australian businesses relying on NAS and RAID systems, this matters because downtime and data loss often overlap. You are not only trying to retrieve files. You may be trying to recover shared folders, databases, virtual machine storage, surveillance footage, or years of project history. RecoveryGeeks handles these scenarios with a service-led focus on preserving data first and avoiding unnecessary risk.
How to reduce the chance of RAID recovery being needed again
The hard truth is that RAID is not a backup strategy. It improves availability in some configurations, but it does not protect against deletion, corruption, ransomware, controller failure, fire, theft, or a bad rebuild. A sensible setup includes tested backups, drive health monitoring, alerting, documented RAID configuration, and a replacement plan for ageing disks.
It also helps to label bays clearly and keep records of disk order, RAID type, and controller settings. Those simple details save time during a failure and can prevent avoidable mistakes when someone is troubleshooting in a hurry.
If your RAID has failed, the safest move is often the least dramatic one: stop, preserve the disks as they are, and get the fault assessed before trying to fix it live. Good recovery work is methodical, and that patience is often what gives your data the best chance of coming back intact.
