
A database recovery example is most useful when it reflects the pressure of a real outage: staff cannot access customer records, orders are stalled, and every attempted fix risks making the situation worse. The right response is rarely to start clicking repair options. It is to stop unnecessary writes, establish what has failed, and recover data in a controlled order.
Consider a representative case involving a Canberra-based engineering business. Its project management system ran on a virtual server, with a Microsoft SQL database stored on a RAID 5 array. On a Monday morning, the system reported database corruption after one disk had failed and a second disk began returning read errors during the rebuild. The business had backups, but the latest clean backup was from Friday night. That meant a straightforward restore could lose a full working day of project notes, timesheets, drawings and job updates.
This is where database recovery becomes more than a restore exercise. The objective is not simply to get a server running. It is to preserve the most current, consistent and usable version of the business data.
Database recovery example: what failed and why
The initial error message pointed to damaged database pages. That was a symptom, not necessarily the root cause. In this case, the database files were affected by an unstable RAID array. Continuing to run database repair tools directly against the live storage could have caused further corruption, especially if the system wrote new data across unreadable or inconsistent areas.
A database relies on structure. Tables, indexes, transaction logs and system metadata must agree with one another. If storage failures interrupt writes, a database may contain records that appear present but cannot be read reliably, or transactions that were only partially committed. A successful recovery therefore needs to address both the underlying media condition and the logical integrity of the database.
The first priority was to take the affected server out of service. Users were asked not to reconnect, and automated processes that might write to the database were stopped. The failed RAID set was then handled as a source device rather than a platform to repair in place.
This decision matters. RAID is designed to provide availability after a limited hardware failure. It is not a substitute for a backup, and it cannot correct every combination of disk errors, controller issues, incorrect rebuilds or file system damage. A degraded array can remain technically online while silently returning incomplete data.
The recovery process
The recovery began with assessment and imaging. Each accessible member disk was examined to establish its condition, sector readability and RAID parameters. Rather than relying on the array to rebuild itself, working copies of the readable data were created wherever possible. This protects the original media and gives the recovery process a stable base for further analysis.
The RAID was then reconstructed virtually using the correct disk order, stripe size, parity rotation and offset. Those details are not interchangeable. A configuration that is slightly wrong can produce files that look plausible but contain scrambled content. For databases, that can lead to misleading results: a file may open, yet key tables or recent records may be invalid.
Once the RAID structure was reconstructed, the database files and transaction logs were extracted to a separate recovery environment. The team checked whether the database engine could recognise the files, then reviewed integrity information and transaction log continuity. The most recent verified backup was also retained as a reference point.
There were three possible recovery paths:
- restore the Friday backup and accept the missing work;
- repair the extracted database files, with a risk that some damaged records would be removed to regain consistency; or
- use the backup as a baseline and recover later transactions from the database and log files where they remained intact.
The third path offered the best outcome, but it depended on the condition of the transaction logs. A transaction log records changes made to the database. When the log is usable, it can help bring an older backup forward to a point much closer to the failure. When it is damaged or incomplete, recovery may still be possible, but the result must be carefully validated.
In this case, the log contained enough consistent data to recover most transactions completed after the Friday backup. A small number of records written during the final storage failure could not be verified. Rather than inserting questionable data into the recovered system, those items were identified and documented for the business to reconcile from emails, job sheets and staff records.
Verification is part of recovery, not an afterthought
A database that starts is not automatically a recovered database. The engineering business needed confidence that its project records, user permissions, attachments and reporting data were correct before staff resumed work.
The recovered copy was tested in an isolated environment. Database consistency checks were run, and the business compared record counts against known figures from the previous week. Staff reviewed recent projects, timesheet entries and critical customer information. The team also tested the application functions that mattered most: creating a job, attaching a drawing, running a report and searching historical records.
This stage can reveal trade-offs. Rebuilding indexes may improve performance but does not restore missing rows. A database repair command may remove corrupt structures to make the database operational, but that can also remove affected data. For a business with compliance, financial or contractual obligations, it is usually better to understand and document any gap than to present a repaired database as complete without evidence.
After verification, the recovered database was deployed to clean storage rather than returned to the original degraded RAID. The business was able to resume operations with nearly all data recovered and a clear list of the few entries requiring manual follow-up.
What this example shows about backups
The business had done something many organisations overlook: it had backups. Yet the incident still created downtime because the backup was not recent enough to meet the business's recovery needs.
Backup planning should begin with two practical questions. How much data can the organisation afford to lose, and how long can it operate without the system? A firm that can tolerate losing one day of updates may be comfortable with nightly backups. A business processing bookings, sales or field work throughout the day may need more frequent backups, transaction log backups, replication or another method of reducing the recovery point.
Backups also need testing. A backup file that exists but cannot be restored is not protection. Periodic test restores should confirm that the database opens, the application connects, and the expected information is present. Copies should be separated from the production environment so a ransomware event, power surge or storage failure does not affect every version at once.
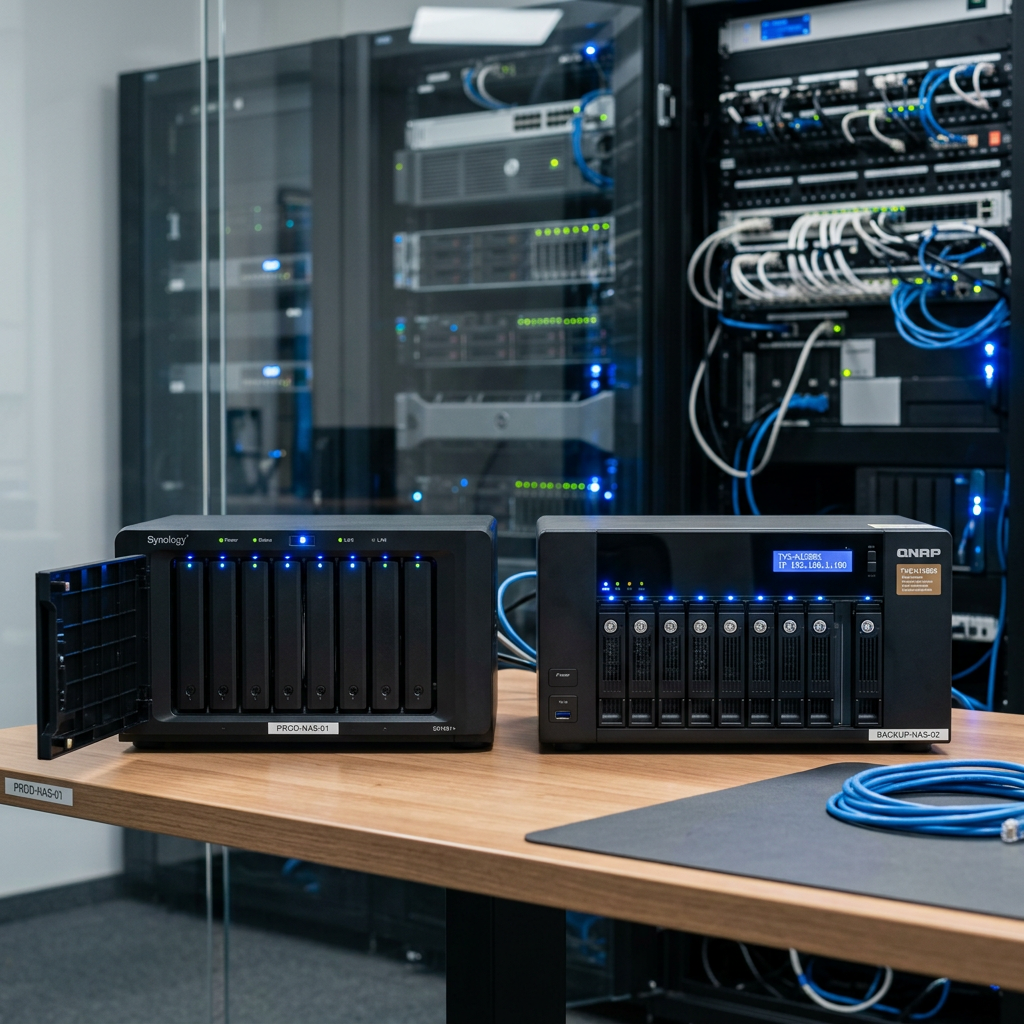
For RAID and NAS environments, monitor disk health and replace failed drives promptly. Do not assume a rebuild is harmless. If an array reports a second failing disk, unusual noises, repeated drop-outs or read errors, switch off the affected equipment where practical and seek advice before initiating another rebuild or repair attempt.
What to do when a database becomes inaccessible
If a database error appears after a power event, failed drive, ransomware incident or server crash, avoid treating the first error message as a diagnosis. Do not install recovery software onto the affected volume, continue using a degraded RAID, or repeatedly run repair utilities without preserving a copy of the current state. Those actions can overwrite evidence needed for a more complete recovery.
Instead, record the error messages, note the time the issue began, identify any recent changes to storage or server hardware, and preserve all available backups and logs. If the database sits on a failed hard drive, SSD, NAS or RAID system, the physical storage issue may need to be addressed before database-level recovery can be assessed.
RecoveryGeeks can assess failed storage media and complex RAID environments where critical database files are inaccessible. For businesses facing an outage, early action gives the best chance of recovering current data while limiting further damage.
The practical lesson is simple: protect the original data first, recover to separate storage, and verify the result with the people who know what the database must contain. That disciplined approach turns a stressful outage into a recoverable incident rather than a permanent loss.
