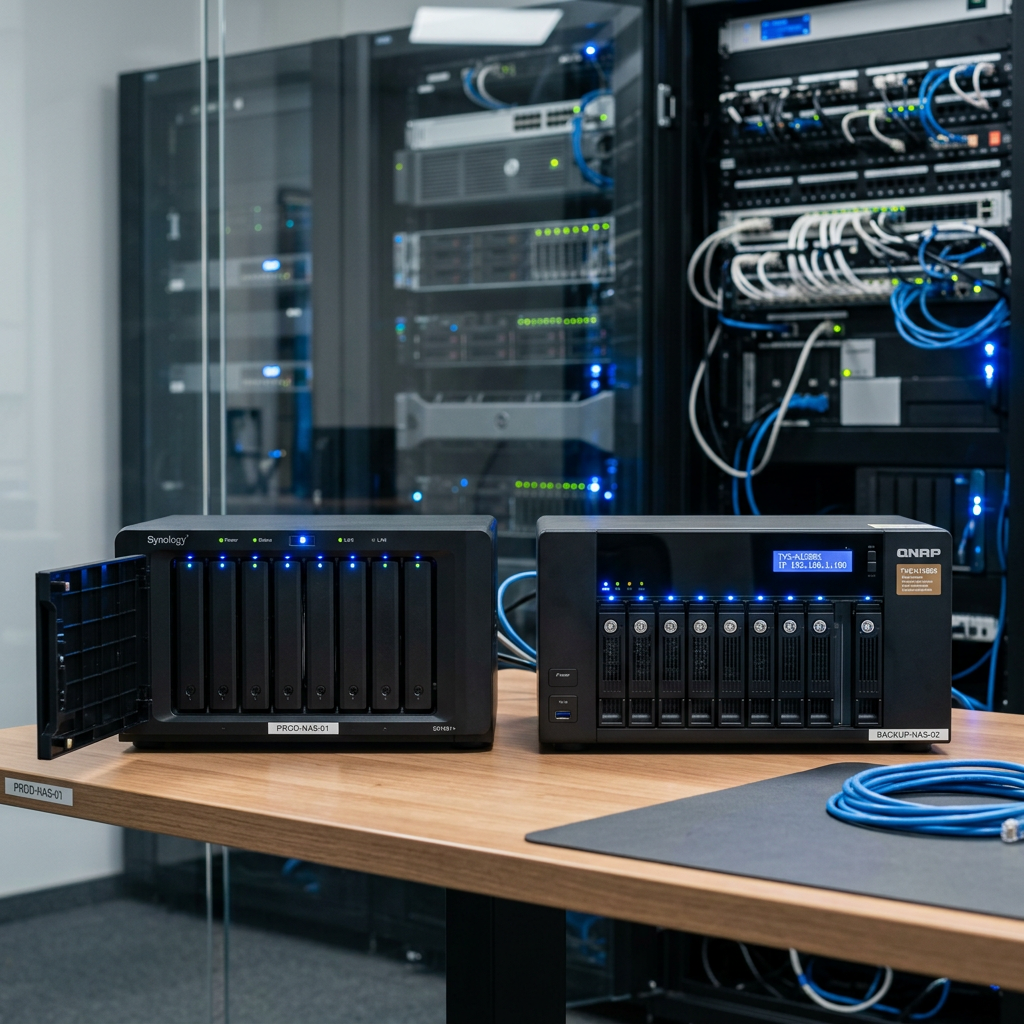

A server failure rarely arrives at a convenient time. Staff cannot access shared files, a line-of-business application stops responding, backups may be unclear, and every attempted fix can change the outcome. This business server recovery guide explains the first decisions Australian organisations should make when critical server data becomes unavailable - whether the issue involves a physical server, virtual machine host, NAS, RAID array, or attached storage.
The immediate goal is not to get the server running at any cost. It is to prevent further damage, establish what has happened, and choose the safest path to restore operations and recover data.
Start by containing the incident
If a server is making unusual clicking, grinding, beeping or repeated spin-up noises, turn it off and leave it off. Those signs can indicate physical drive failure. Continuing to restart the server or run repair utilities may cause a weakening drive to deteriorate further, reducing the amount of recoverable data.
For a system that is powered on but inaccessible, avoid making broad changes under pressure. Do not initialise disks, format volumes, rebuild a RAID array, reinstall the operating system, or accept prompts to "fix" an unfamiliar file system. These actions can write new information over metadata and data that a recovery process may need.
Separate the technical problem from the operational problem. Record which services are affected, when the fault was first noticed, any error messages, recent changes, and the names of staff who have interacted with the system. Screenshots and photos of controller messages, drive bay indicators and console errors can be useful, especially if the server must be moved or powered down.
Where practical, restrict access to the equipment. A well-meaning staff member may swap drives, disconnect cables or repeatedly reboot a machine in an effort to help. In a RAID or NAS environment, changing the order of drives is a particular risk. Label each drive with its bay position before it is removed, and keep the set together.
Identify the type of failure before choosing a fix
A server can be unavailable for many reasons, and the right response depends on the failure category. A network fault, expired certificate, failed power supply or application configuration issue may leave data untouched. A failed drive, corrupted file system, ransomware event or RAID controller fault calls for a different level of caution.
Physical storage failure
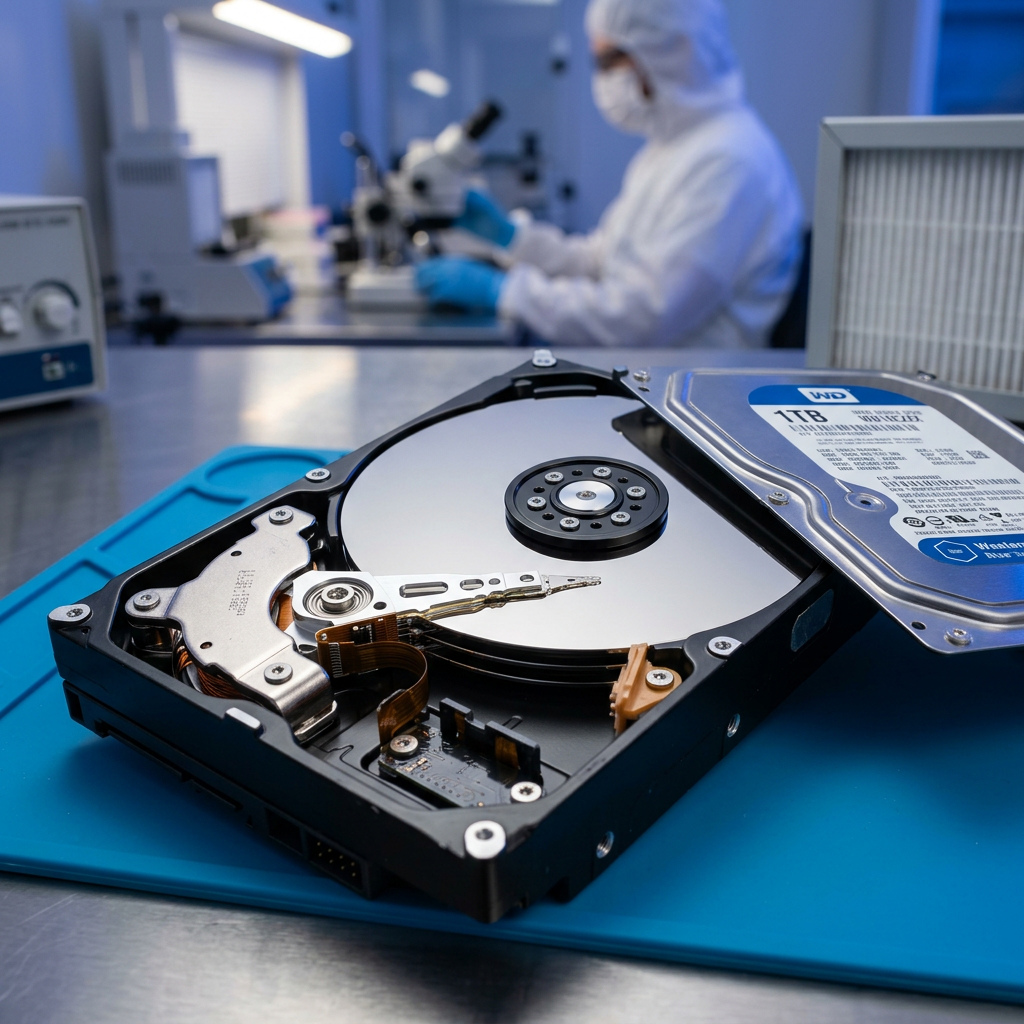
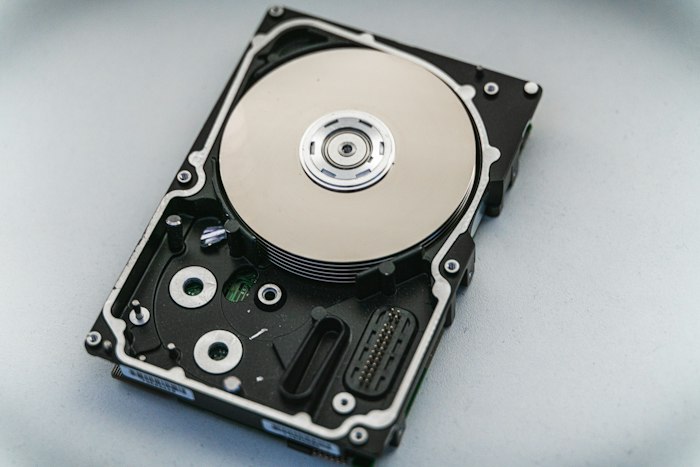
Physical faults occur when a hard drive, SSD, controller, power component or connection fails. Traditional hard drives may develop read errors or mechanical damage. SSDs can fail suddenly due to controller, firmware or NAND flash problems, sometimes becoming inaccessible with little warning.
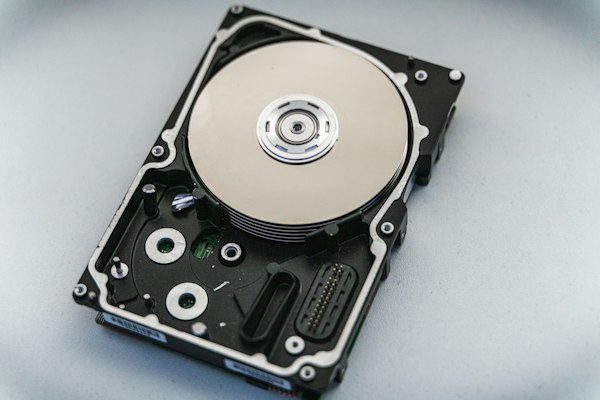
If the storage device is unstable, focus on preserving its condition. Do not open a hard drive, freeze it, or run consumer recovery software against the original device. Professional recovery work commonly begins by creating a controlled copy of readable sectors, allowing analysis to take place without placing further stress on the source media.
Logical corruption and accidental deletion
Logical failures include deleted folders, damaged partitions, corrupted databases and file system errors. The hardware may appear healthy, but the data structure that tells the operating system where files are stored is damaged or altered.
The key trade-off is between rapid restoration and preservation. If there is a verified, recent backup, restoring it to clean replacement storage may be the fastest way to resume service. If the backup is incomplete, old, untested or potentially affected by the same event, stop and assess before overwriting the original server volumes.
RAID, NAS and virtual server faults
RAID provides resilience, not a substitute for backup. An array can become unavailable after multiple disk failures, a failed controller, interrupted rebuild, incorrect drive order, firmware issue or corrupted configuration. RAID 5 and RAID 6 arrays may be especially vulnerable during rebuilds because every remaining drive is placed under sustained load.
NAS devices bring similar risks, even where multiple disks are present. Their operating systems, volume managers and proprietary configurations can complicate recovery. Virtual environments add another layer: a failed datastore, damaged virtual disk file or host issue may affect many servers at once. Avoid creating new virtual machines or writing files to an affected datastore until the recovery position is clear.
Make a recovery decision based on business impact
Not every incident needs the same response. First, determine the recovery point objective: how much recent data can the business afford to lose? Then determine the recovery time objective: how long can each service remain unavailable?
A payroll database, practice management system, customer records platform or production file share may justify immediate specialist assessment. A non-critical archive server may allow more time to validate backups and plan a controlled restore. This distinction helps technical teams prioritise work without treating every system as equally urgent.
Check backups carefully rather than assuming they are usable. Confirm the most recent successful backup date, whether the required application data is included, where the backup is stored, and whether a restore has been tested. A backup job marked successful does not always mean the files are complete or recoverable. For database-driven systems, confirm that transaction logs, application settings and encryption keys are also available.
If ransomware is suspected, isolate affected systems from the network immediately. Preserve the ransom note, file extensions, timestamps and relevant logs, but do not contact the attacker from a compromised system. Avoid deleting encrypted files or wiping the server before evidence and recovery options have been assessed. Your incident response process may also require notification to management, insurers, legal advisers or cyber security specialists.
What not to do during server data loss
The most costly mistakes are often made in the first few hours. Avoid these actions unless they are part of an approved and tested incident procedure:
- Repeatedly rebooting a server with suspected drive failure.
- Rebuilding, reinitialising or formatting a degraded RAID or NAS volume.
- Replacing multiple RAID drives at once or mixing up their bay order.
- Running repair commands that write changes to the only copy of affected data.
- Restoring over original disks before confirming backup quality and recovery requirements.
- Using unverified recovery tools on production storage.
There are exceptions. An experienced IT team may need to fail over a clustered service, replace a known faulty power supply or restore a tested backup to alternate infrastructure. The point is to make those changes deliberately, with the original data preserved wherever possible.
Prepare the server for specialist assessment
When the data is commercially sensitive, the hardware is physically failing, or a RAID, NAS or virtual infrastructure is involved, professional assessment can prevent an avoidable loss. Provide clear information: server make and model, operating system, RAID level, number and order of drives, controller details, encryption status, symptoms, recent events and the specific folders, databases or systems that matter most.
Do not remove drives from their caddies unless necessary for safe transport. Keep them in their original order, label positions, and protect them from knocks and static. If a device has been exposed to water, fire or impact, do not attempt to power it on. Place it in a clean, dry, protective container and arrange assessment promptly.
RecoveryGeeks provides expert professional data recovery for business hard drives, SSDs, NAS and RAID systems, including cases where standard IT troubleshooting is no longer the safe option. For Canberra organisations and businesses across Australia, early assessment can clarify whether data can be recovered, what the likely risks are, and how to avoid compromising the remaining evidence.
Build the lessons into your recovery plan
Once the immediate incident is controlled, review why it was difficult. Many businesses discover that their backup strategy covered files but not the full server configuration, that recovery credentials were held by one person, or that no one had documented the RAID layout and application dependencies.
A useful plan identifies system owners, critical services, backup locations, encryption keys, vendor contacts and escalation authority. It should also set out who can approve a restore, when to involve a recovery specialist, and how staff communicate downtime to customers. Test the plan with a real restore exercise, not just a checklist review.
For high-value systems, maintain more than one recovery option. A local backup may restore quickly after accidental deletion, while an isolated offsite copy can protect against ransomware, theft or site damage. The appropriate design depends on your budget, data sensitivity, acceptable downtime and the cost of losing a day's work.
When a server fails, calm handling is a technical control in its own right. Preserve the original state, verify what can be restored, and seek specialist help before a recoverable fault becomes a permanent loss.
