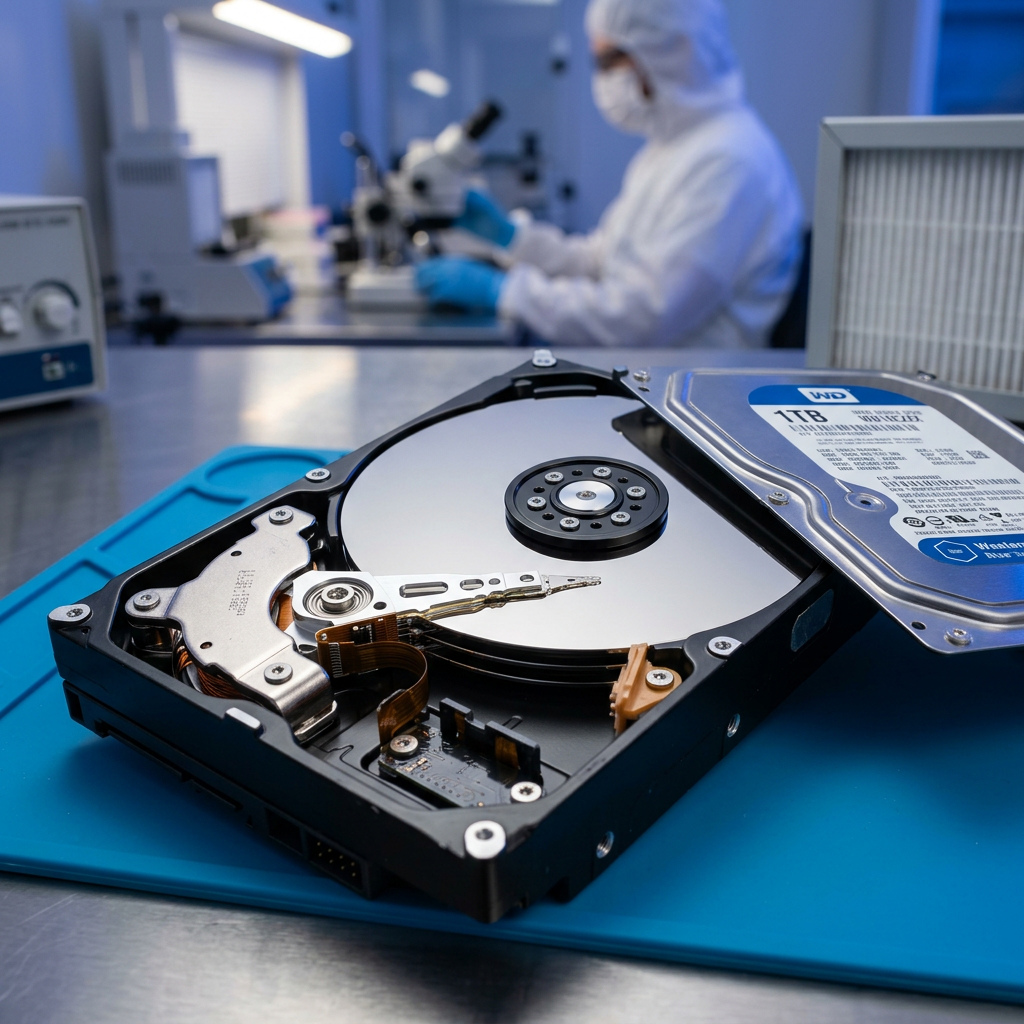
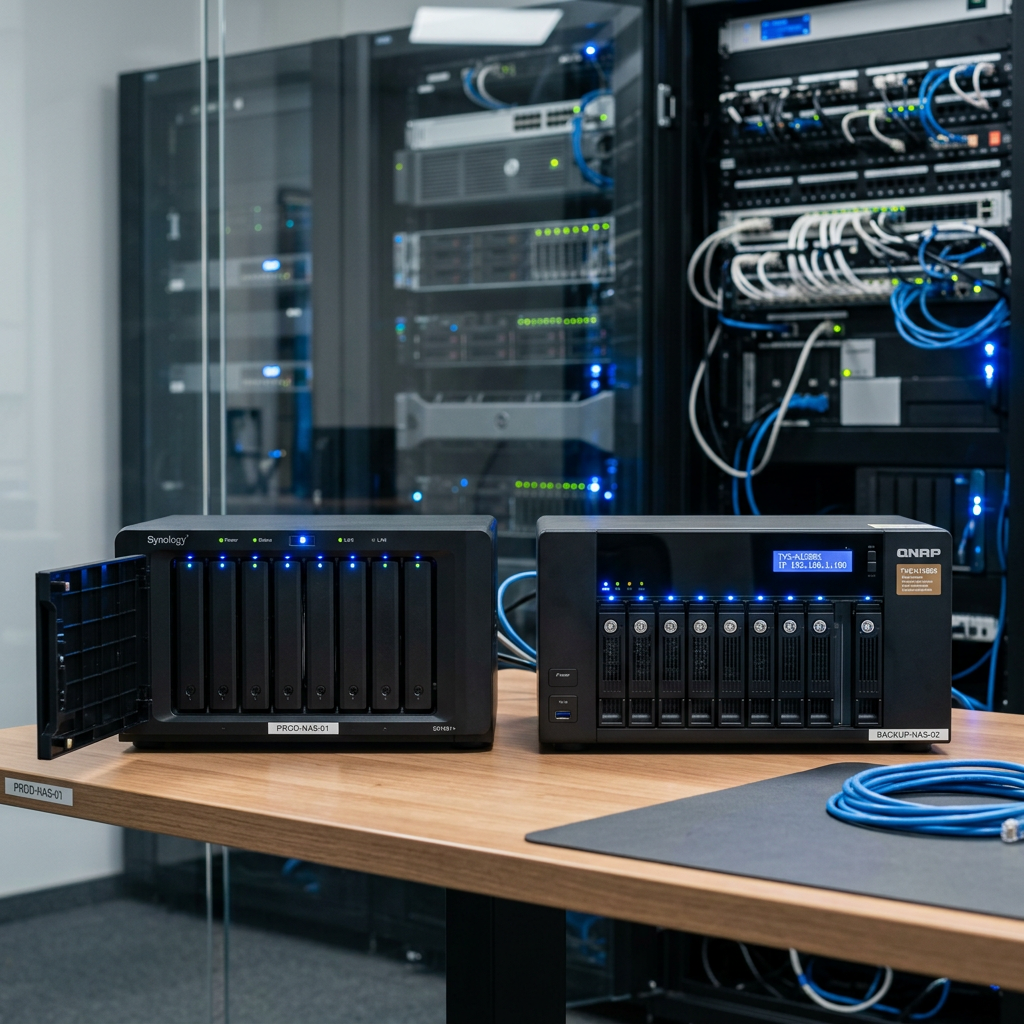

A RAID failure can look deceptively simple: one red drive light, a NAS that will not mount, or a server volume that has suddenly disappeared. In practice, the wrong response can turn a recoverable fault into a far more complex incident. This business RAID data recovery guide explains what to do when company data becomes inaccessible, what not to do, and when specialist recovery is the safer option.
Business RAID data recovery guide: protect the array first
RAID is designed to improve availability, performance, or both. It is not a backup. Even arrays with redundancy can fail when more drives are affected than the RAID level can tolerate, a rebuild is performed incorrectly, the controller loses its configuration, or file system corruption damages the logical volume.
The first priority is to preserve the current state of the array. If the data is critical and the system has become inaccessible, stop non-essential activity. Continued writes may overwrite metadata, parity information or files that are still recoverable. This is particularly relevant to NAS devices hosting shared folders, accounting data, project files, virtual machines or database backups.
Avoid treating an array failure as a routine drive replacement until the cause is clear. A failed disk in a healthy RAID 5 array is one situation. A degraded array with a second unstable disk, repeated drop-outs or an incomplete rebuild is another. Those scenarios require different decisions.
Actions to take immediately
- Record any error messages, drive bay numbers, warning lights and recent changes to the system.
- Shut down the affected server or NAS cleanly if it is unstable, repeatedly restarting, making unusual noises or dropping drives.
- Label every drive by its physical bay position before removing anything. Drive order often matters during reconstruction.
- Keep the RAID controller, NAS chassis, caddies and cables with the drives where possible.
- Prevent users and applications from writing to the affected volume.
- Check whether a current, separate backup exists before attempting any repair action.
If the system remains online but is degraded, consider whether it is genuinely safe to keep operating. The answer depends on RAID level, number of failed or suspect drives, workload, backup status and the value of the data. A heavily used RAID 5 array with one failed drive and another showing read errors should not be pushed through normal business activity simply because it is still available.
Identify the type of RAID failure
A sound recovery plan begins with identifying whether the issue is physical, logical or configuration-related. These faults can overlap, which is why a device may report several confusing symptoms at once.
Physical failures involve the drives themselves. Conventional hard drives may develop bad sectors, fail to spin, click, or become slow and unreliable. SSDs can fail electronically or present corrupted data after controller or firmware issues. Power events can affect several drives at once, particularly in NAS and server environments without effective power protection.
Logical failures occur where the disks are readable but the data structure is not. Examples include accidental deletion, corrupted file systems, ransomware, failed firmware updates, damaged NAS operating systems and lost partitions. The raw data may still exist across the member disks, but it needs careful reconstruction.
Configuration failures are common after controller replacement, migration, accidental reinitialisation, or a mistaken attempt to create a new array. RAID data is distributed according to a specific layout: disk order, stripe size, parity rotation, offset, RAID level and controller behaviour. A recovery process must determine those parameters accurately before files can be extracted.
Why rebuilds can make recovery harder
A rebuild is intended to restore redundancy after replacing a failed drive. It is not a data recovery process. During a rebuild, the system writes reconstructed data across a replacement disk. If the original diagnosis was wrong, if another member disk is weak, or if the array contains file system corruption, the rebuild may introduce further changes to evidence needed for recovery.
This is especially risky with RAID 5. Rebuilding places sustained read demand on every surviving disk. An older disk with developing read problems may fail under that load. RAID 6 provides tolerance for two drive failures, but it is not immune to controller faults, accidental formatting, multiple unreadable areas or corrupted array metadata.
Do not force an offline array online, initialise foreign disks, accept an option to format a volume, or create a new RAID set using the original drives. Prompts may appear harmless or even promise to repair the system, but they can write new metadata over the existing configuration.
A useful rule is simple: if the data is valuable enough that loss would disrupt operations, image and assess the original drives before any repair or rebuild attempt. A working copy gives recovery technicians a safer basis for reconstruction and protects the originals from additional stress.
Gather the details a recovery specialist needs
Good information reduces delays and helps determine the safest path. You do not need to diagnose the RAID yourself, but your IT team can preserve details that are difficult to recreate later.
Record the NAS or server make and model, RAID controller model, drive capacities and serial numbers, RAID level, number of bays, and which bays were reporting faults. Note whether the array was RAID 0, 1, 5, 6, 10 or a proprietary NAS configuration. Also retain screenshots of administration alerts, event logs and any messages shown before the outage.
Describe what happened immediately before access was lost. A power failure, firmware update, failed disk replacement, accidental deletion, malware event or controller change can point to very different recovery methods. If a technician has already attempted a rebuild or replaced drives, provide that history as well. It is better to disclose unsuccessful steps than to guess at the array’s original condition.
For encrypted systems, make sure authorised staff can access encryption keys, passwords and recovery information. Data recovery can restore an array structure, but encryption remains effective when the necessary credentials are unavailable.
Common business RAID scenarios
A two-bay NAS in RAID 1 may survive a single-drive failure, but data can still be inaccessible if the remaining disk has file system errors or the NAS enclosure fails. In some cases, each disk holds a readable copy; in others, the vendor’s partition layout and encryption require more careful handling.
A RAID 5 file server commonly fails after one disk drops out and a second drive starts reporting read errors. Replacing the first disk and beginning a rebuild may be tempting. If the second disk is deteriorating, a controlled recovery from images of all drives is often less risky than forcing a full rebuild.
RAID 10 can tolerate certain drive failures, but not every two-drive combination. If both failed drives belong to the same mirror pair, the array may be unavailable. Correct disk identification and preservation of drive order are essential.
Virtualisation adds another layer. A RAID array may appear intact while the files holding virtual machines are corrupted. The recovery goal then may be to restore specific virtual disks, databases or documents rather than bring the original server straight back into production.
When professional RAID recovery is the right call
Professional assistance is warranted when multiple drives have failed, the array was reformatted or reconfigured, a rebuild has failed, disks make mechanical noises, the controller cannot recognise the array, or the data supports day-to-day business operations. It is also prudent where the only backup is outdated, incomplete or untested.
Specialist recovery work typically starts by assessing each drive and creating stable working images where possible. Technicians then analyse RAID metadata and test the array parameters in a controlled environment. Once the correct layout is established, recovered files can be validated and supplied on suitable media. The aim is to extract usable business data without making avoidable changes to the original disks.
For Canberra organisations and businesses elsewhere in Australia, RecoveryGeeks can assess failed RAID and NAS storage where critical files, shared data or business records are no longer accessible. Before arranging service, keep the drives labelled, bring relevant hardware where available, and provide the incident details collected by your IT team.
Recovery is only one part of resilience
After a recovery, do not return to normal operations by simply copying files back onto the same untested storage. Identify why the failure occurred. Review drive age, SMART alerts, cooling, power protection, firmware practices, controller health and whether alerts were acted on early enough.
Most businesses benefit from a backup design that keeps more than one copy, uses separate storage or a separate location, and is tested through real restoration exercises. The right design depends on your recovery time target, data volume, internet connection and compliance obligations. A small office may need a simple managed backup plus a local copy, while a larger operation may require immutable backups, versioning and documented disaster recovery procedures.
The calmest response to RAID data loss is a disciplined one: stop unnecessary writes, preserve every drive and detail, and choose the next action based on evidence rather than urgency alone.
